To build a searchable database for a news site, model your stories, authors, topics and publication status as relational tables in PostgreSQL, load a clean export from your CMS, then attach a weighted full-text search index and expose it through a parameterized endpoint. Most newsrooms finish the core build in a day or two, and readers get keyword search plus faceted filters in return.
A searchable database for a news site is a structured collection of records — stories, documents, ad buys, public records — stored so readers can query it with keywords and filters instead of scrolling, and exposed on your pages through a search box and a sortable, filterable table.
That matters because a newsroom’s most valuable material usually ends up stranded in a spreadsheet that no reader can reach. Publishing it turns flat data into something people cite, link back to and return to, while your desk keeps control over what appears and what doesn’t.
The rest of this guide walks through the build in order: what you need, the schema, the import, the search configuration, the endpoint, the tests, and the launch. Everything assumes a small team without a dedicated engineering department.
Table of Contents
- What You Need
- Step-by-Step: How to Build a Searchable Database for a News Site
- 1. Model the Data: Stories, Authors, Topics and Status
- 2. Import and Normalize Editorial Content
- 3. Add Full-Text Search and Useful Indexes
- 4. Build a Safe Search Endpoint for the News Site
- 5. Test Relevance, Performance, and Editorial Edge Cases
- 6. Deploy, Monitor, and Maintain the Search Database
- Common Mistakes
- Frequently Asked Questions
- Conclusion
What You Need
Six things, and only one of them is hard to learn. If you can write a SELECT statement, you can finish this.
The minimum stack
- PostgreSQL 16. It ships with full-text search, trigram matching, generated columns and a query planner that stays honest as an archive grows.
- A newsroom content export. A CSV or JSON dump from your CMS or story database: headline, byline, body, section, timestamps, URL, status.
- pgAdmin 4 or another schema-design tool, so you can see table relationships and run queries without touching a terminal.
- The psql command-line client, which ships with PostgreSQL. It is the fastest way to load large CSVs.
- A short list of real reader queries. Write down ten things readers actually type into your current archive search. These become your test set in step 5.
- An HTTPS application environment that can run a small Node or Python service and hold a database connection string outside the code.
If your CMS already keeps content in a database you can query, skip the export and connect to a read-only replica. Never point migrations at the live editorial database.
Before installing anything, write down who owns the data. On a small desk that is one editor, and naming them now saves an argument later about who fixes a stale record.
Step-by-Step: How to Build a Searchable Database for a News Site
Six stages, in this order, each ending with a check you can run before moving on. The mistakes that break most builds come last.
1. Model the Data: Stories, Authors, Topics and Status
Start by translating editorial needs into entities, not tables. A newsroom thinks in stories, bylines, desks, embargoes and corrections. The database should hold the same concepts with stable identifiers.
Four entity types cover most desks: the story, the person who wrote it, the topic it belongs to, and the section it appears in. Everything else — campaign ads, court filings, council minutes — becomes a story with a different document type attached.
CREATE TABLE author (
  id          bigserial PRIMARY KEY,
  slug        text NOT NULL UNIQUE,
  display_name text NOT NULL,
  created_at  timestamptz NOT NULL DEFAULT now()
);

CREATE TABLE story (
  id            bigserial PRIMARY KEY,
  canonical_id  text NOT NULL UNIQUE,   -- from the CMS, never reissued
  slug          text NOT NULL UNIQUE,
  headline      text NOT NULL,
  dek           text,
  body_text     text NOT NULL,
  summary       text,
  url           text NOT NULL UNIQUE,
  status        text NOT NULL DEFAULT 'draft'
                CHECK (status IN ('draft','scheduled','published','embargoed','withdrawn','corrected')),
  embargo_until timestamptz,
  published_at  timestamptz,
  corrected_at  timestamptz,
  created_at    timestamptz NOT NULL DEFAULT now(),
  updated_at    timestamptz NOT NULL DEFAULT now(),
  search_tsv    tsvector GENERATED ALWAYS AS (
                  setweight(to_tsvector('english', coalesce(headline,'')), 'A') ||
                  setweight(to_tsvector('english', coalesce(dek,'')),     'B') ||
                  setweight(to_tsvector('english', coalesce(summary,'')),  'C') ||
                  setweight(to_tsvector('english', coalesce(body_text,'')), 'D')
                ) STORED
);

CREATE TABLE story_author (
  story_id  bigint NOT NULL REFERENCES story(id) ON DELETE CASCADE,
  author_id bigint NOT NULL REFERENCES author(id),
  position  smallint NOT NULL DEFAULT 1,
  PRIMARY KEY (story_id, author_id)
);

CREATE TABLE topic (
  id   bigserial PRIMARY KEY,
  slug text NOT NULL UNIQUE,
  name text NOT NULL
);

CREATE TABLE story_topic (
  story_id bigint NOT NULL REFERENCES story(id) ON DELETE CASCADE,
  topic_id bigint NOT NULL REFERENCES topic(id),
  PRIMARY KEY (story_id, topic_id)
);

CREATE TABLE user_role (          -- who may see unpublished rows
  id         bigserial PRIMARY KEY,
  username   text NOT NULL UNIQUE,
  role       text NOT NULL CHECK (role IN ('reader','editor','admin'))
);
Three decisions in that schema do most of the work later. The canonical_id carries the identifier your CMS already assigned, so a story keeps its identity through every import and correction. The status column plus the CHECK constraint means a draft can’t quietly go live because someone forgot a filter. And splitting authors and topics into join tables stops a byline change from rewriting 400 rows.
Verify the model with a real editorial question before you import anything else. Pick an author and a date range:
SELECT s.headline, s.published_at, s.url
FROM story s
JOIN story_author sa ON sa.story_id = s.id
JOIN author a ON a.id = sa.author_id
JOIN topic t ON t.slug = 'climate'
JOIN story_topic st ON st.topic_id = t.id AND st.story_id = s.id
WHERE a.slug = 'r-okafor'
  AND s.published_at >= '2026-01-01'
  AND s.published_at <  '2026-07-01'
  AND s.status = 'published'
ORDER BY s.published_at DESC;
If that returns the right set on a hand-built table of twenty rows, the relationships are right. Get this wrong and every downstream import inherits the mistake.
2. Import and Normalize Editorial Content
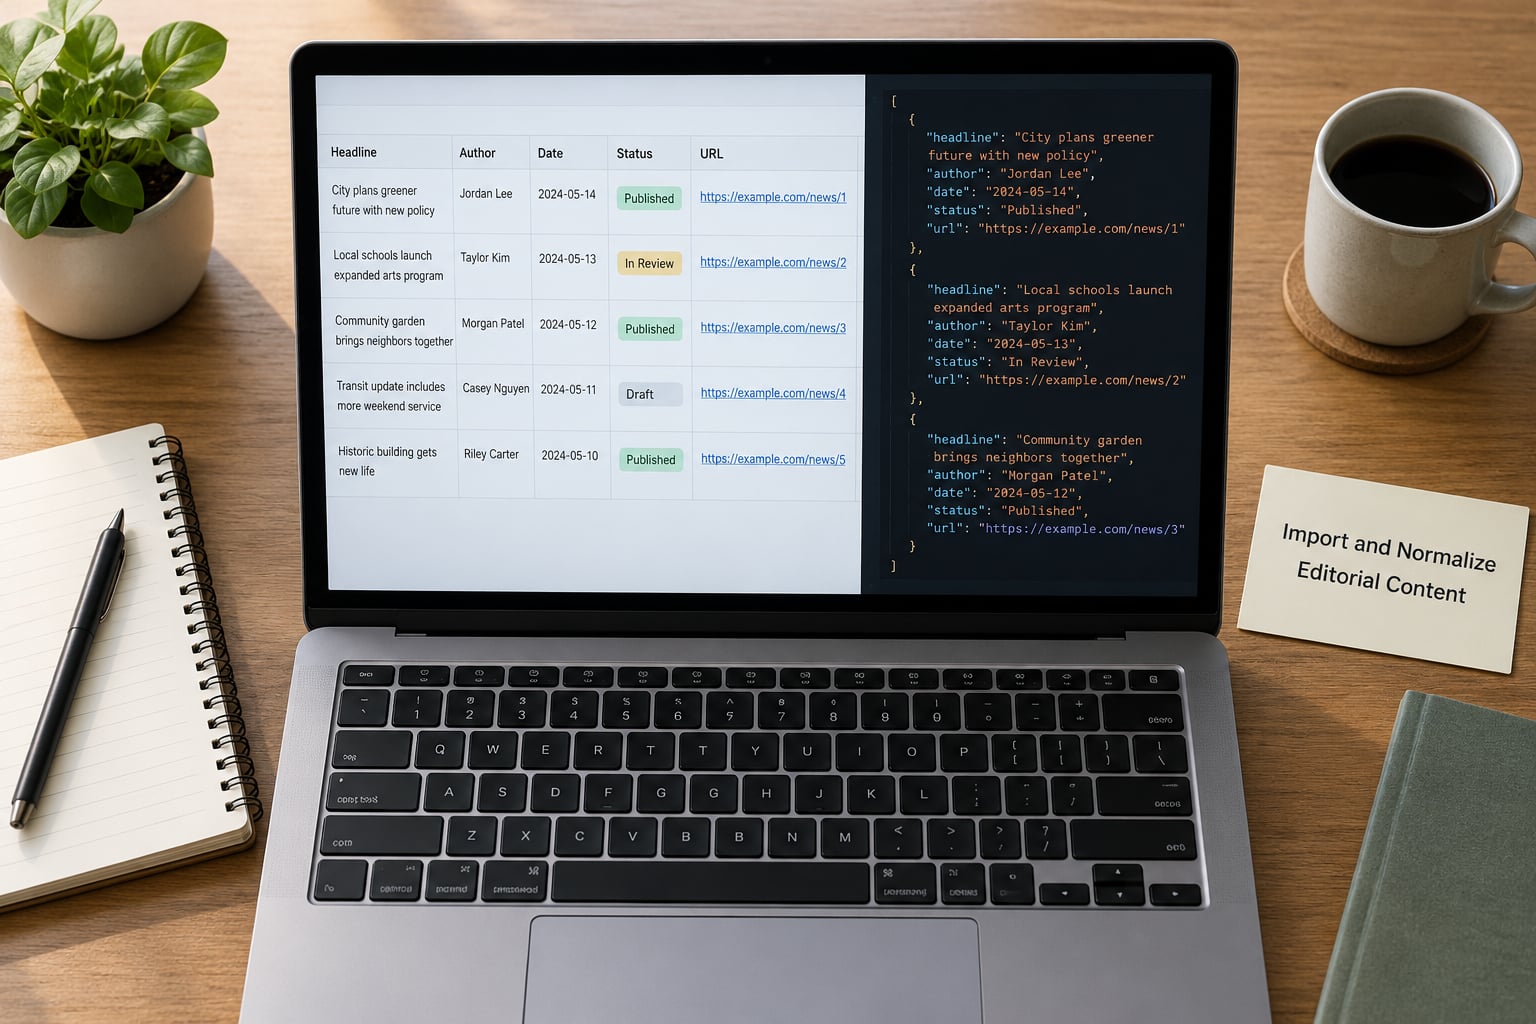
Never import straight into the tables your search reads. Load into a staging table first, clean there, then promote. That one habit turns a broken import into a five-minute fix instead of a weekend of cleanup.
CREATE TABLE staging_story (
  canonical_id text,
  slug         text,
  headline     text,
  dek          text,
  body_text    text,
  summary      text,
  url          text,
  status       text,
  published_at text,
  updated_at   text,
  author_slugs text,
  topic_slugs  text
);

copy staging_story FROM 'newsroom_export.csv' WITH (FORMAT csv, HEADER true, ENCODING 'UTF8')
Exporters produce surprises. Timestamps arrive in at least four formats, body text arrives with smart quotes and stray HTML entities, bylines arrive as one string where the schema wants two rows, and status arrives spelled five different ways.
Run these checks before promoting anything:
- Encoding. Force UTF-8 on load and normalize typographic quotes in
body_text. Mojibake in the archive is permanent once readers link to it. - Missing headlines.
SELECT count(*) FROM staging_story WHERE headline IS NULL OR btrim(headline) = ''; - Invalid dates. Parse into
timestamptzin staging and count the failures rather than guessing a default. - Duplicate URLs. The
UNIQUEconstraint will catch them at promotion time, which is the point — see them first. - Orphaned bylines. Compare author slugs in the export against the
authortable and create the missing ones deliberately. - Unpublished rows. Count them. You want a number you can recite, because that’s what protects the embargo.
Promote with one repeatable transaction, so a rerun is harmless:
BEGIN;

INSERT INTO author (slug, display_name)
SELECT DISTINCT unnest(string_to_array(author_slugs, ';')) AS slug,
       initcap(replace(unnest(string_to_array(author_slugs, ';')), '-', ' '))
FROM staging_story
ON CONFLICT (slug) DO NOTHING;

INSERT INTO story (canonical_id, slug, headline, dek, body_text, summary, url, status, published_at, updated_at)
SELECT canonical_id, slug, headline, dek, body_text, summary, url,
       lower(status), published_at::timestamptz, updated_at::timestamptz
FROM staging_story
WHERE headline IS NOT NULL AND btrim(headline) <> ''
ON CONFLICT (canonical_id) DO UPDATE
  SET headline    = EXCLUDED.headline,
      body_text   = EXCLUDED.body_text,
      status      = EXCLUDED.status,
      published_at= EXCLUDED.published_at,
      updated_at  = now();

COMMIT;
Keying the upsert on canonical_id is what makes re-syncs safe. Run it after every export and nothing duplicates.
A newsroom-specific detail: keep a corrections side table from day one. A correction published six months later should update the same record, not create a second one.
3. Add Full-Text Search and Useful Indexes
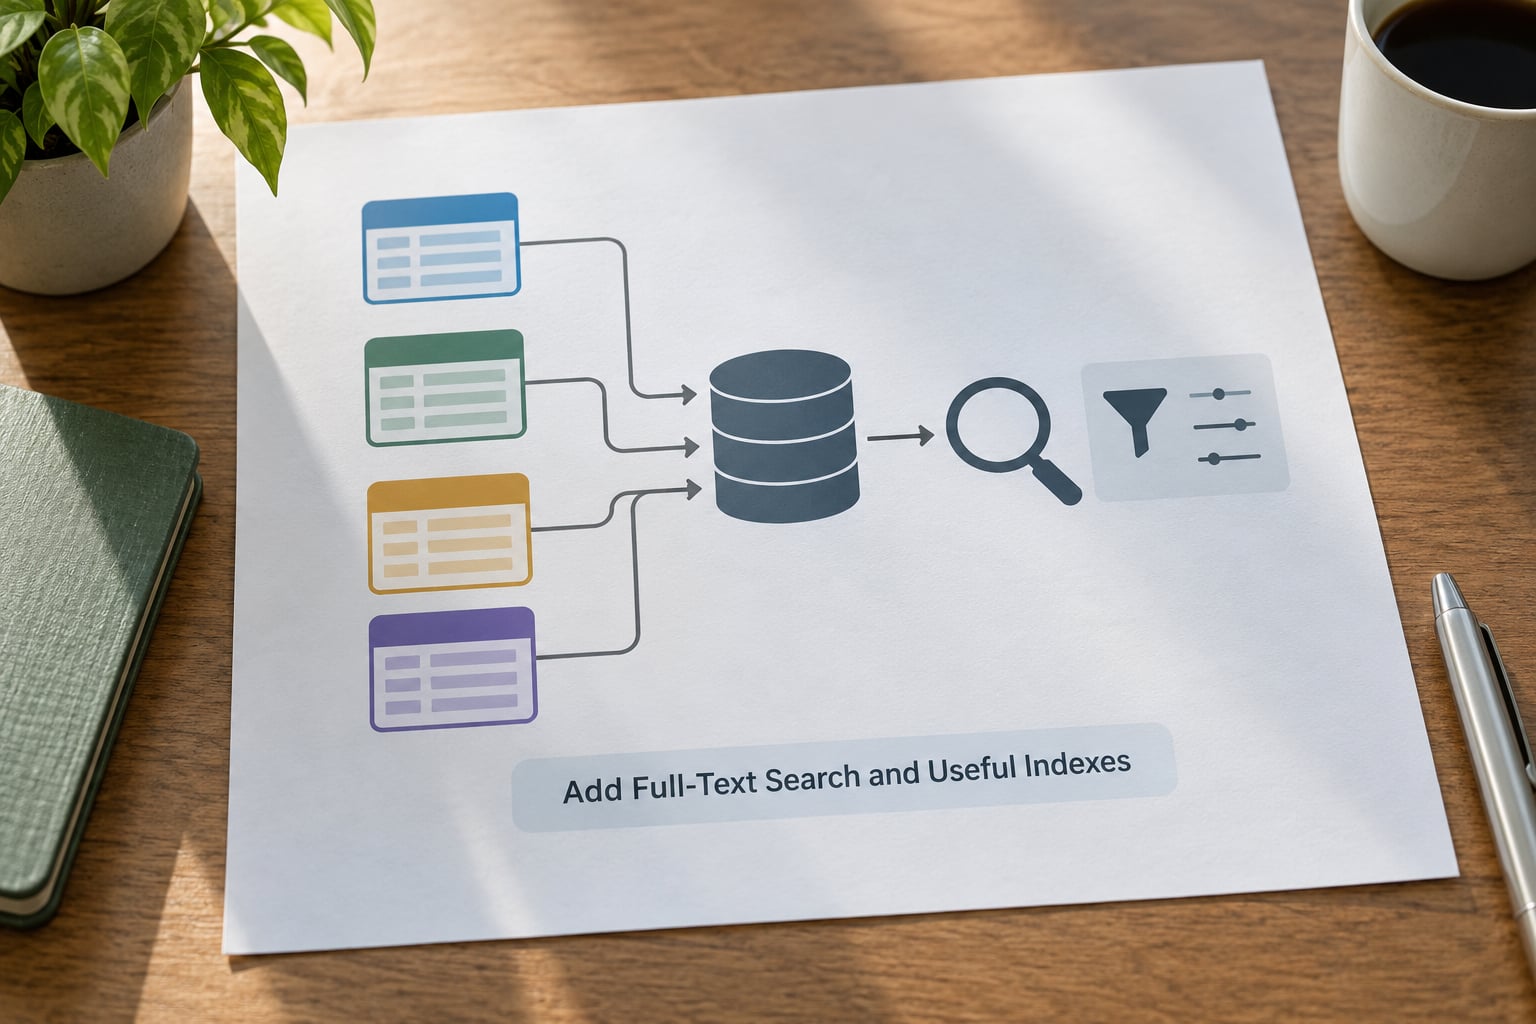
The search_tsv column from step 1 already holds a weighted vector, so a headline match outranks a body-text match automatically. Now index it and give readers the query surface.
CREATE INDEX story_search_tsv_idx ON story USING GIN (search_tsv);
CREATE INDEX story_status_pub_idx ON story (status, published_at DESC);
CREATE INDEX story_author_story_idx ON story_author (author_id, story_id);
CREATE INDEX story_slug_trgm_idx ON story USING GIN (slug gin_trgm_ops);
CREATE INDEX story_headline_trgm ON story USING GIN (headline gin_trgm_ops);
That GIN trigram index is the fix for two reader behaviours: partial titles and misspelled names. Trigram matching handles “tran” matching “transportation” without any synonym list.
The query a reader’s keystrokes become looks like this:
SELECT s.id, s.headline, s.url, s.published_at,
       ts_headline('english', s.search_tsv, websearch_to_tsquery('english', $1)) AS rank,
       ts_headline('english', s.search_tsv, websearch_to_tsquery('english', $1),
                   'MaxWords=24, MinWords=8, ShortWord=2, HighlightAll=false') AS snippet
FROM story s
WHERE s.status = 'published'
  AND s.published_at <= now()
  AND s.search_tsv @@ websearch_to_tsquery('english', $1)
  AND ($2::bigint IS NULL OR s.id > $2::bigint)
ORDER BY rank DESC, s.published_at DESC
LIMIT 25;
Use websearch_to_tsquery, not to_tsquery. It handles quoted phrases, negation and OR the way a reader expects, and it won’t throw a syntax error on a stray apostrophe.
Every clause is a bound parameter — $1, $2 — never string concatenation. That single habit is the difference between a search box and a database hole in your site.
Validate with the planner rather than guessing:
EXPLAIN (ANALYZE, BUFFERS)
SELECT ... ;  -- paste the real query with real parameters
Look for Bitmap Index Scan on story_search_tsv_idx. If you see Seq Scan on a table with tens of thousands of rows, your filter order is wrong — narrow by status and date before the text match, or add a combined index.
PostgreSQL alone stays the right answer through roughly a hundred thousand stories, with faceted filters and a handful of editors. OpenSearch earns its place when you need typo tolerance across languages, per-field boosting that changes by section, faceting on more than a dozen dimensions, or a search box that must span content from several systems at once. That’s usually a daily archive site in year three, not launch week.
4. Build a Safe Search Endpoint for the News Site
The database never talks to the browser. A small server-side service takes a query string, validates it, runs the parameterized statement, and returns JSON.
export async function GET(req) {
  const url    = new URL(req.url);
  const q      = (url.searchParams.get('q') || '').slice(0, 200).trim();
  const section= url.searchParams.get('section') || null;
  const cursor = url.searchParams.get('cursor') || null;

  if (!q && !section) return Response.json({ results: [] });

  const params = [q || '', cursor ? Number(cursor) : null, section];
  const { rows } = await pool.query(SQL, params);   // $1 $2 $3 — never interpolated

  return Response.json({
    results: rows.map(r => ({
      id: r.id, headline: r.headline, url: r.url,
      published_at: r.published_at, snippet: r.snippet
    })),
    next_cursor: rows.length === 25 ? rows[rows.length - 1].id : null
  }, { headers: { 'Cache-Control': 'public, max-age=60' } });
}
Four rules keep this safe for a news site. Cap input length at the edge, cap results at 25 per page, and cache public responses briefly so a traffic spike from a popular story doesn’t become a database outage. Always filter on status = 'published' in the public query, and never connect the public service with credentials that can read drafts.
Put rate limiting on the route, not the database. A crawler hitting /search?q= a thousand times an hour is a normal Wednesday; a naive loop over 200,000 rows per keystroke is not.
Database credentials belong in environment variables on the host, never in a JavaScript bundle or a repository. A news site with reader search is a site holding unpublished material, and the connection string is the whole perimeter.
5. Test Relevance, Performance, and Editorial Edge Cases
Build the test set from real queries, not invented ones. Twenty of them is enough, drawn from your site search logs if you have them.
Cover exact headlines, misspelled names, partial titles, multi-word phrases, author bylines, date ranges, topic filters, synonyms a reporter uses that readers won’t (“transit” versus “buses”), and queries that should return nothing.
Then add the editorial edge cases that break quietly: a withdrawn story that still ranks, a correction whose text changed, an embargoed story scheduled for next week, a URL that changed during a redesign, and a duplicate that arrived through a second export path.
-- These must all return zero rows for a reader-role request
SELECT count(*) FROM story WHERE status IN ('draft','scheduled','embargoed');
-- And these should return the corrected text, not the old version
SELECT headline, corrected_at FROM story WHERE status = 'corrected' ORDER BY corrected_at DESC LIMIT 5;
Set a response-time target you can actually measure — 200 milliseconds at the 95th percentile is a reasonable line for a single-node PostgreSQL install — and check it with EXPLAIN ANALYZE before launch, not after a traffic problem.
When a result is wrong, fix the cause rather than the symptom. A withdrawn story ranking means the status filter is missing, not that you need a bigger index. A misspelled byline not matching means no trigram index on that column, not a bad synonym list.
6. Deploy, Monitor, and Maintain the Search Database
Launch is the easy part if migrations are versioned. Every schema change goes into a numbered migration file, applied to staging first, then production in a transaction that can be rolled back on failure.
Back up daily with pg_dump, keep two weeks, and test a restore once a quarter. An archive nobody has restored is not a backup.
Monitor four things: uptime, query duration at the 95th percentile, import job success, and zero-result query rate. That last one is the most useful number in the list — it’s your list of things readers looked for and your archive doesn’t have.
Plan the re-sync rhythm before you go live. A daily export with an upsert keyed on canonical_id handles most corrections and URL changes. Trigger a re-index after large CMS migrations instead of letting search serve stale records for a week.
Run REINDEX or VACUUM ANALYZE on a schedule once the archive is large enough for autovacuum to lag. Set an alert when an import job fails; a silent import failure is the failure mode that damages reader trust fastest, because it looks like the archive is simply empty.
Launch checklist:
- Every unpublished record verified inaccessible through the public endpoint
- Ten real reader queries return correct results
- Search page loads under three seconds on a mid-range phone
- Keyboard navigation reaches the search box and every filter
- Restored backup tested this quarter
- One named person owns the record and the re-sync
Common Mistakes
Ten errors show up repeatedly, each with the fix that actually resolves it.
- Indexing raw markup. Store plain text in
body_text; tags and entity soup make relevance scores meaningless. Parse once at import. - Storing only headlines. Search the dek, summary and body too — they’re weighted lower, not excluded.
- Weighting every field equally. Use A/B/C/D weights so a headline hit outranks a passing mention.
- Skipping status filters. One missing
WHERE status = 'published'leaks drafts. Make it a default in the query, not a per-endpoint habit. - Using LIKE on a large collection. It works on 5,000 rows and crawls at 500,000. Switch to the tsvector column and a GIN index.
- Importing duplicates. Key on the CMS identifier and upsert, so a rerun of the same export changes nothing.
- Exposing unpublished content. Separate read-only public credentials from editorial ones, and treat search as a publishing surface.
- Skipping pagination limits. Cap at 25 results and require a cursor. Unbounded result sets are how a search box becomes an outage.
- Ignoring encoding. Force UTF-8 on load. Fixing mojibake after publication means broken permalinks and reader reports.
- Launching without query tests. Twenty real queries, run before you promote. Relevance is a design decision, not something to discover from complaints.
Two more worth naming. Don’t over-build — most archives serve readers perfectly well from PostgreSQL plus a handful of indexes, and a separate search cluster you don’t need is a system nobody maintains. And decide early who edits records. Practitioners building on spreadsheet tools report the same friction constantly: the data lands fine, and then nobody knows who is supposed to update it.
A useful weekly habit: export your zero-result queries and your top searches. Thirty seconds of maintenance each week tells you what to commission next month.
Frequently Asked Questions
What database is best for a searchable news site?
PostgreSQL is the default answer for most newsrooms. It handles full-text search with field weighting, trigram matching for typos, and it handles millions of rows without extra infrastructure. Managed hosts keep the maintenance load low. Reach for a hosted no-code tool instead when no one on staff wants to own a server, and reserve OpenSearch for very large archives or complex multilingual boosting.
Can I build news-site search with PostgreSQL alone?
Yes, for the vast majority of sites. A tsvector column, a GIN index and a parameterized query cover keyword search, phrase search, ranking and pagination. Add trigram indexes for misspellings and a simple table for filter values, and you have faceted search too. You will still need a small server-side endpoint so browsers never hold database credentials.
How often should the news database search index update?
As often as your content changes, which for most desks means a daily export with an upsert keyed on your CMS identifier. Corrections and URL changes should flow through the same job rather than a manual fix. Keep search results cached for about a minute so readers see near-live content without a write per keystroke.
When should a news site use OpenSearch instead of PostgreSQL?
Move when you need typo tolerance across several languages, per-field boosting that changes by section, faceting across more than a dozen dimensions, or one search box spanning content from multiple systems. Those are real needs for large daily archives. For a typical story archive of under a hundred thousand posts, PostgreSQL stays faster to operate and far cheaper to maintain.
How can a searchable news database protect unpublished stories?
Give the public endpoint a database role that physically cannot read draft, scheduled or embargoed rows, and put the status filter in the default query rather than relying on developers to remember it. Separate the editorial credentials entirely, keep embargo expiry as a timestamp the query checks, and never expose connection strings in browser code or version control.
Conclusion
Start with an inventory, not an install. Write down what records you want to expose and the ten queries readers actually type, because those two lists decide your schema and your test set.
Then build the smallest thing that works: a PostgreSQL database, three tables, a hand-loaded export of twenty real stories, and one weighted tsvector column. Prove the search answers those ten queries, wire it to a parameterized endpoint, run the unpublished-content checks, and only then automate the daily import and put it on the page.
That sequence keeps every decision reversible, and the archive stays something your desk can maintain.