To deal with missing values in a story dataset, measure them field by field, work out why each one is blank, then choose between labelling the gap, dropping the row, dropping the field, or filling it with an estimate — and write the choice down. On a small CSV that is an afternoon’s work, and it is the difference between a published figure you can defend and one a reader can pull apart.
A blank cell is not a zero. It is a question: did nobody record this, did somebody refuse, did the agency withhold it because the underlying count was small, or did your import break halfway through a merge? Each answer deserves a different treatment, and all of them quietly change the denominator of whatever average, percentage or ranking you publish next.
Sources spell the same gap a dozen ways — empty, NA, N/A, NULL, -, 999, “unknown”, “refused” — and newsroom data usually arrives through a spreadsheet or a join, which manufactures fresh blanks nobody audits afterwards. Here is the workflow I use before a number goes anywhere near a chart.
What You Need
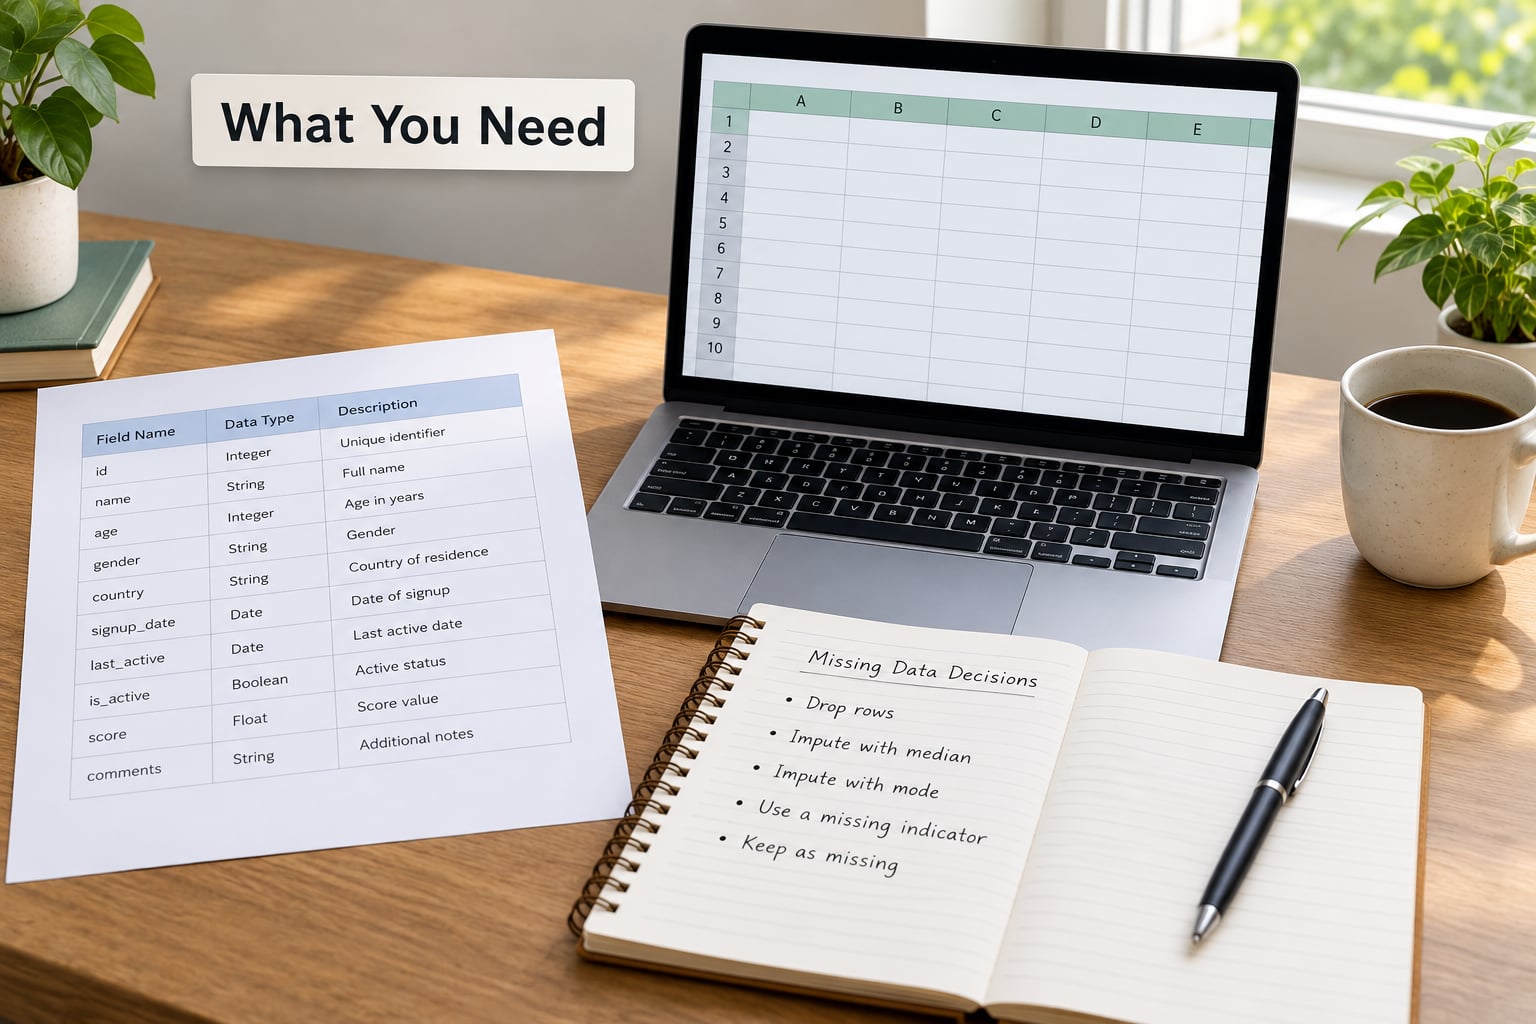
Five things, and none of them expensive. If you have the first three, the rest is a fifteen-minute setup.
- The dataset exactly as you received it, plus a duplicate you never open. Every fix happens on the copy, so you can always go back and ask what the source actually said.
- A data dictionary or the documentation page from whoever published the data. Agency suppression thresholds, code lists and field definitions live there, and they tell you what a blank is allowed to mean.
- The research question in one sentence. “How many permits were issued this year” and “which neighbourhoods saw permits fall” tolerate different levels of missingness.
- A tool that shows you nulls honestly. A spreadsheet will do for a small file; pandas in Python or base R in R will do for anything larger. Both flag blanks natively — the risk is in the display, not the tool.
- A decision log: a text file, a sheet or a query that records which fields you treated, what you did to them and how many rows changed. You will need it for the methodology note and for the reply to the source who spots your number.
One more thing that costs nothing: find out whether your file was combined with anything else. Joins, lookups and pivots are the most common source of blanks that nobody meant to create.
Step-by-Step: How to Deal with Missing Values in a Story Dataset
The order matters more than the code. Measure first, classify second, treat third, validate last. Skip the classification step and a bias walks straight into your headline wearing a spreadsheet’s clothes.
1. Define What Counts as Missing
A missing value is a cell that should hold a fact and holds nothing. Before counting anything, decide what counts, because real files disagree about it constantly.
| What you see in the file | What it usually means | How to normalise it |
|---|---|---|
Empty cell or NA | Not recorded | Already a null |
N/A, NULL, - | Placeholder for the same idea | Convert to null |
0, -99, 999 | Often a zero stored as a code, sometimes a real zero | Check the data dictionary before touching it |
| “unknown”, “refused”, “don’t know” | A respondent answered, and the answer was no | Keep as its own category, not a null |
| Blank on a field that does not apply | Structural, not informative | Leave blank and say why |
| Repeated row | A duplicate, not a gap | De-duplicate first, then re-count |
The distinction that catches people out is “refused” versus “not recorded”. One is a finding — people declined to answer, and that is worth a sentence in the story. The other is an absence. Collapsing both into a null throws away the more interesting of the two.
import pandas as pd

df = pd.read_csv("incidents.csv")
blank_markers = ["", "NA", "N/A", "NULL", "-", "999", "unknown", "refused"]
df = df.replace(blank_markers, pd.NA)
Run that once, before your first count, and check the row count. If it changes you have just deleted records you did not mean to touch, and that is the moment to find out why.
2. Measure the Missingness
Now count. A column that is 60% blank is a broken field; 6% of rows missing one optional date is a Tuesday. The same percentage means different things in different places.
missing_pct = df.isnull().sum() / len(df) * 100
print(missing_pct.sort_values(ascending=False).head(10))

rows_with_any_gap = df.isnull().any(axis=1).sum()
print(rows_with_any_gap, "of", len(df))
R does the same in one line: colSums(is.na(df)) / nrow(df) gives you the per-column rate, and sum(!complete.cases(df)) gives you the rows.
Read every number against its denominator, and write the denominator next to it. “Income missing for 240 of 1,180 respondents” is a fact a reader can weigh. “20% missing” is a number floating free of the population it came from.
Then check the fields that should never be blank. A date of birth, an ID or a location that is 30% empty usually points at an import problem rather than a reporting gap, and that is a bug, not a statistic.
3. Check Whether Missingness Is Random or Systematic
Why a value is missing matters more than how many are missing. The standard framing comes from Little and Rubin and splits into three cases, but the plain version is short enough for a methodology note.
- Missing completely at random. The blanks have nothing to do with the record’s other values — a dropped packet, a keying error, a random export glitch. Here, dropping the affected rows costs you sample and little else.
- Missing at random. The blank is predictable from something you already have. Rural addresses fail to geocode more often than urban ones, so region predicts the gap even though region itself is not the outcome.
- Missing not at random. The blank is itself informative. This is the case that quietly rewrites a story, and no imputation method can rescue it.
Suppressed government cells are the cleanest example of the third kind. When an agency withholds a figure because the count is too small to publish safely, the missing value is not random at all — it is a bounded one, and everything you can see sits above the threshold. A user on r/AskStatistics described exactly this shape in a thread about redacted data: every surviving value sat at or above the same cutoff, which tells you far more than the blanks do.
The practical test is cheap: cross-tab the missing flag against a variable that matters to your story — sex, age band, region, year — and look for a pattern.
df["no_income"] = df["income"].isna()
df.groupby("region")["no_income"].mean().sort_values()
If one region is missing at twice the rate of the others, deleting those rows quietly deletes a place from your map, and your “regional” finding becomes an artefact of who filled in the form.
4. Choose a Treatment for Each Pattern
Six methods cover almost every newsroom dataset. The right one depends on what the field is for and how badly a wrong value would distort the story.
| Method | Best for | Risk to the story | Rule of thumb |
|---|---|---|---|
| Keep and label | Categorical fields, refusals, unknowns | Denominator shrinks unless you publish the gap | Add an explicit “Unknown” category or a missingness flag |
| Listwise deletion | Small gaps, records missing one optional field | Removes whole records, unevenly across groups | Under 5% and you can report what you dropped |
| Drop the column | Fields mostly empty or suppressed | You lose the variable entirely | Do not build a story on a field you had to remove |
| Mean, median or mode fill | Quick descriptive statistics | Smooths variance and can tilt an average | Median over mean for skewed counts |
| Group-aware or regression fill | A field that varies by subgroup | Propagates group differences you never measured | Fill from the group’s own median, never the column’s |
| Multiple imputation | Formal analysis where you publish uncertainty | Overkill for most published charts; easy to misreport | Run the analysis many times, pool with Rubin’s rules |
Filling is one line. Grouping is two, and it is the difference between a defensible estimate and a bad one.
df["income"] = df["income"].fillna(df["income"].median())

region_median = df.groupby("region")["income"].transform("median")
df["income"] = df["income"].fillna(region_median)
df["income_was_missing"] = df["income_was_missing"].fillna(True)
In R the equivalent of skipping blanks in a summary is mean(x, na.rm = TRUE); be aware that this changes the denominator, so report how many observations it ran over.
Thresholds give you a starting point rather than a verdict. Below roughly 5% missing, dropping rows is usually cheap. Between 5% and 20%, impute and add a missingness flag. Between 20% and 40%, impute only with a strong model and report the gap in the text. Above 40%, treat the field as unusable and go find another source. The mechanism still overrides the percentage every time.
Whichever you pick, run the sensitivity check: recompute your headline number with the affected records excluded and again with them filled. If the two answers land on different sides of a round figure, readers will find the difference before you do.
5. Validate the Result
Validation is not the same as cleaning. You are checking that the treatment did not quietly change the story.
- Re-run every total, mean and count that appears in the piece and compare them with the source’s own published figures.
- Check the arithmetic that changed: if you dropped 12% of rows, a rate calculated on the remainder is a rate about 12% larger than the same rate on the full set.
- Inspect the edges. The smallest categories and the newest dates are where fills go wrong, because a fill leans hardest on thin groups.
- Plot the filled distribution against the raw one. Mean and median fills flatten the histogram in a way that is visible at a glance and dishonest in a chart.
- Write each treatment into your decision log with the count it affected.
Then add one sentence to the methodology note: how many records had gaps, which fields were affected, what you did about them, and where the source itself withheld information. That sentence costs you nothing and it is the difference between a caveat and a correction.
Common Mistakes
These five come up in almost every newsroom dataset I have looked at, and each one produces a number that looks fine until someone checks it.
Filling blanks with zero. Zero means nothing happened; a blank means we do not know. Swapping them turns “no permits recorded” into “no permits issued”, and it drags every average toward the floor. Fix: check the data dictionary for placeholder codes before assuming anything, and treat a documented code such as -99 as a null.
Deleting every incomplete row. It is fast, and it is how an entire neighbourhood disappears from a map. Fix: run the subgroup cross-tab in step 3 first, and if the gaps concentrate anywhere that matters to your angle, delete nothing.
Counting blanks as observations. Any average, percentage or ranking computed without an explicit denominator silently treats “unknown” as a value. Fix: state the denominator for every published figure, and where gaps are substantial, show them as their own category in the chart.
Imputing facts you cannot support. A regression fill produces a plausible number, which is exactly the problem: plausible is not sourced. Fix: only fill where you can explain the estimate in one sentence and name the inputs it came from.
Skipping the post-merge audit. A join that does not match leaves whole columns blank for every unmatched row, and the pattern usually traces the join key rather than the subject. Fix: after every merge, re-run the per-column missing count and compare it with the count from before the merge.
Before you publish, confirm four things: every published number has a stated denominator; the decision log matches what the code actually did; the chart shows unknown as a category rather than hiding it; and the methodology note tells the reader how many records were affected.
Frequently Asked Questions
What is the 5% missing data rule?
The 5% rule is a convention, not a law: if fewer than about 5% of values in a variable are missing, dropping those rows usually costs you little in precision. Past that, deletion starts shrinking the sample and can strip out whole subgroups unevenly. Treat the number as a starting point, because the reason a value is missing matters more than the percentage itself.
Should I drop rows with missing values?
Only after you check where the missingness sits. If blanks are spread evenly and affect under roughly 5% of records, dropping them is a reasonable choice, provided you say how many you removed. If they concentrate in one region, age band or year, deleting those rows deletes the group your story may be about, so keep them and label them instead.
Is mean or median better for imputation?
Median, almost always, for counts and money. The mean is dragged around by a handful of large values, so filling with it pulls small observations upward, and filling with it also flattens the spread of the finished distribution. Use the mean only when the field is roughly symmetrical, and never fill a categorical field with a number, use the most frequent category instead.
What is the difference between zero and missing?
Zero is an observation: we checked and nothing was there. Missing is the absence of an observation: nobody checked, the record was withheld, or the import dropped it. Filling blanks with zero invents real measurements of nothing, which drags totals and averages down and can turn an unknown into a finding. If a source stores zero as a code such as -99, translate the code, not the concept.
How do I report missing data to my audience?
Say it plainly in the methodology note and near the chart: how many records had gaps, which fields were affected, what you did about them, and where the source itself suppressed information. Where gaps are large enough to matter, show them as their own bar or category rather than dropping them out of the denominator. A visible gap costs less credibility than a number that quietly moves.
Conclusion
Start by mapping the gaps: which fields, how many rows, and which groups they cluster in. That map tells you whether the missingness is random, partly random or informative, and that answer — not any threshold — decides whether you label the gaps, drop rows, drop the field or fill it.
Write the treatment down before the number goes near a headline, and tell the reader what you did. A story with a visible gap is harder to criticise than a story with a silent one.