A newsroom data pipeline is an automated, repeatable process that collects data from a source, cleans and standardises it, stores a versioned copy, and publishes it somewhere reporters or readers can use it. Built properly, nobody re-downloads the same spreadsheet every morning, and every published number can be traced back to the file it came from. This guide is for a small newsroom doing editorial data work, not for broadcast or streaming media IT.
To build a simple data pipeline for a newsroom you need six things and about a weekend: one recurring task worth automating, a source you can actually get, a place to keep the untouched original, a cleaning step, a schedule, and a check that tells a human when something is wrong. The hard part is not the tooling. It is deciding what the output has to look like before you write anything.
Start with data you already have. Plenty of newsroom pipelines begin with a CSV someone exported by hand, and getting that file through a repeatable process teaches you more than a speculative platform build. Beginners stall because the starting point is ambiguous, not because the tools are hard.
Table of Contents
- What You Need
- Step-by-Step: How to Build a Simple Data Pipeline for a Newsroom
- Common Mistakes
- Frequently Asked Questions
- What is the easiest way to build a data pipeline for a small newsroom?
- Do I need Python or a developer to build a newsroom data pipeline?
- Should a newsroom use an API, CSV file, or spreadsheet as its data source?
- How often should a newsroom data pipeline refresh its data?
- How can journalists tell whether automated newsroom data is accurate?
- When should a newsroom pipeline be rebuilt or replaced?
What You Need
The minimum viable stack is unglamorous, and that is the point. Everything below has a free option that works for a single-source pipeline.
- A clearly defined data source. An API, a downloadable file, a public dashboard or a newsroom-maintained record. Not “whatever exists”.
- A destination for the cleaned output. A CSV file, a Google Sheet, a SQLite database or a small JSON file on your site.
- A spreadsheet or database. Google Sheets for the early stages, a database once the file outgrows a spreadsheet.
- A transformation tool. A spreadsheet’s built-in formulas, OpenRefine for messy records, or Python with pandas if you expect to run it more than once.
- A scheduling method. A cron job on a server, or a scheduled GitHub Actions workflow if your code already lives in a repository.
- Documentation. A plain file describing the source, the fields, the last refresh and who owns it.
Most of this needs no technical support. The point where you want a developer is when the source has no usable download, when it rate-limits aggressively, when the story depends on a real-time feed, or when the cleaned file feeds something audience-facing. If the answer to “can I get the whole file in one request” is no, that is the moment to ask for help.
Step-by-Step: How to Build a Simple Data Pipeline for a Newsroom
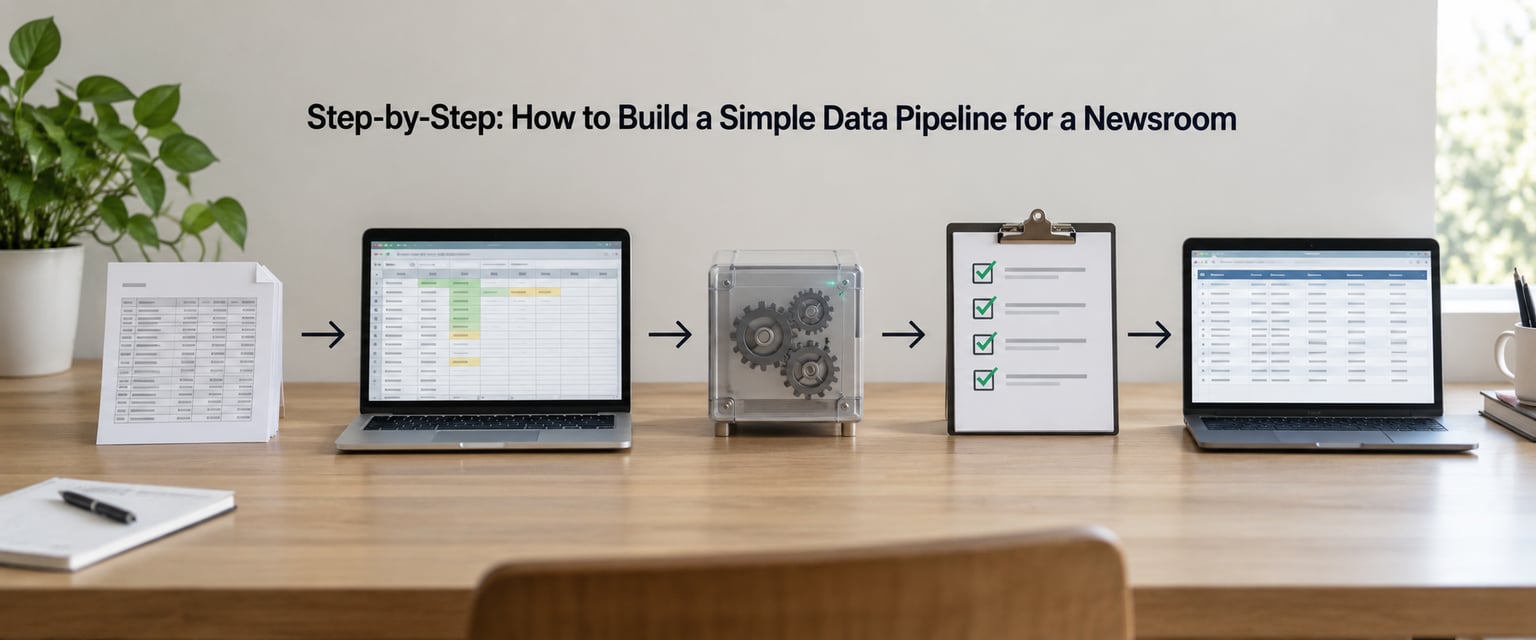
The path runs from raw source data to a validated, newsroom-ready file in six stages: acquire, extract, clean, store, publish, verify. The verify step is the one generic data-engineering definitions leave out, and in a newsroom it is the one that protects you.
1. Define the Data Task and Output
Turn the newsroom need into a specific question with a specific output. “Track council votes” is not a specification. “One row per vote, with date, motion number, sponsor, outcome and the vote count as a fraction” is.
Write down five things before touching the data: the output fields, the row structure, the update frequency, who reads the output, and what decision it informs. Election results, restaurant inspection records, city budget lines and public health alerts all make good first pipelines because they are small, tabular and already public.
You know the specification is complete when a colleague could take your output file and write a story from it without emailing you a question. If they would need to ask what a field means, the data dictionary is missing.
2. Choose a Reliable Source
Check six things about any candidate source: who publishes it, how often it updates, whether the terms permit programmatic access, whether there is a rate limit, whether the documentation explains the fields, and whether you can get the full dataset rather than a paginated slice.
Public dashboards are the awkward case. Many are built on tools that load data from behind a login, so the visible chart and the underlying data are not the same thing. Before committing, check whether the agency publishes an open data file or whether an information request will get you one. For records that exist on paper anyway, a formal request is often faster and always safer than scraping a page you were never given.
Also check whether the licence allows republishing. Government open-data portals usually do, with attribution. A commercial database that happens to be visible behind a login usually does not.
3. Collect and Store the Raw Data
Store the original file, untouched and timestamped, every run. This is the rule that separates a pipeline from a folder of downloads, and it is what lets you answer “where did this number come from?” six months later.
import requests, datetime, pathlib

url = "https://example.gov/data/violations.csv"
stamp = datetime.datetime.now().strftime("%Y%m%d-%H%M")
dest = pathlib.Path("raw") / f"violations-{stamp}.csv"

dest.parent.mkdir(exist_ok=True)
response = requests.get(url, timeout=30)
response.raise_for_status()
dest.write_bytes(response.content)
print(f"saved {len(response.content)} bytes to {dest}")
Two rules here. Never overwrite a raw file, and never write cleaned data into the same folder. Keep raw/ and clean/ separate, and turn on versioning if your storage supports it. Versioning gives you a rollback path when a source quietly changes its format and you publish a chart of nonsense for six hours.
If the source is a spreadsheet you export manually, keep doing that manually for the first few runs. Once you have watched three cycles, you will know which fields actually change.
4. Clean and Transform the Data
Do the minimum transformation that makes the data usable, and nothing else. Renaming columns, coercing types, parsing dates, removing duplicates, filling or flagging missing values, and standardising place names covers almost every newsroom case.
import pandas as pd

df = pd.read_csv("raw/violations-latest.csv")
before = len(df)

df = df.rename(columns={"insp_date": "date", "facility": "name"})
df["date"] = pd.to_datetime(df["date"], errors="coerce")
df["score"] = pd.to_numeric(df["score"], errors="coerce")
df = df.drop_duplicates(subset=["name", "date"])
df = df.dropna(subset=["date", "score"])

assert len(df) <= before, "cleaning added rows, something is wrong"
print(f"{len(df)} rows kept, {before - len(df)} dropped")
That last assertion matters more than it looks. A transformation that silently adds or removes rows is how a wrong number reaches publication. Log the row count before and after every run, and keep the dropped rows in a separate file rather than deleting them.
Geographic normalisation is the step people skip and then regret. “SPRINGFIELD”, “Springfield” and “Springfield City” are three values in one field, and every map and every per-city total breaks on them. A crosswalk file fixes it once.
5. Automate the Update and Add Quality Checks
Schedule the run at a time that matches how fast the source updates, not how fast you want fresh numbers. A weekly council dataset does not need a job that runs every hour. Run the collection and cleaning together, and only when the collection succeeded.
A crontab line is often enough on a server:
17 6 * * * cd /srv/pipeline && python run.py >> logs/run.log 2>&1If you would rather not touch a server, GitHub Actions runs the same command on a schedule from a repository, with the run log and any failure visible in the interface. Either way, the checks are the actual work.
Add four checks and make them fail loudly rather than quietly:
- Freshness. If the newest record is older than it should be, alert. A stale feed is a missed story.
- Schema. Confirm the expected columns still exist. New agencies rename fields without warning, which is what schema drift looks like in practice.
- Row count. Compare against the previous run. A drop to zero usually means the scraper returned an empty response rather than that the world had no violations.
- Impossible values. Negative counts, scores outside a known range, dates in the future.
Send the failure to a person, not a log file nobody opens. An email or a channel message at six in the morning is what lets a reporter fall back to the previous day’s file and still make the deadline.
6. Publish a Newsroom-Ready Output
Export to whatever the downstream tool reads. A CSV or Google Sheet suits analysis and quick charts. A JSON file suits a page that embeds it directly and updates itself. A database view suits anything with a real query layer. Keep the output format boring, because the interesting work already happened upstream.
Then write the documentation that travels with it: the source and its licence, the refresh time, the transformations applied, the known caveats, and the name of the person who owns it. A short README in the same repository takes ten minutes and prevents the pipeline from becoming the thing only one person understands.
Before publication, spot-check a handful of rows against the source by hand. You are not verifying the whole dataset; you are confirming that the column you are about to quote still means what it meant last month.
Common Mistakes
Most newsroom pipelines fail for boring reasons, and nearly all of those failures are cheap to prevent.
- Undocumented sources. Someone bookmarks a dataset and forgets where it came from. Fix: every source gets a line in one file, with the URL, the licence and the date someone last confirmed it works.
- Overwriting raw data. The downloader writes to the same filename every run and yesterday’s version is gone. Fix: timestamp the filename and turn on storage versioning.
- Assuming the schema is stable. A column gets renamed overnight and the pipeline either crashes or, worse, keeps running with a null column. Fix: check expected columns on every run and fail if one is missing.
- Skipping validation. No checks means a broken run looks exactly like a quiet news day. Fix: freshness, row count, schema and value-range checks, all alerting a person.
- Scheduling too aggressively. Running hourly against a source that updates weekly wastes effort and burns through rate limits. Fix: match the schedule to the source’s real update cadence.
- Publishing misleadingly cleaned values. Zero became missing, which became zero, and the chart says something false. Fix: keep dropped and coerced rows in a separate audit file, and never silently coerce.
- Unclear ownership. The person who built it moves on, and the pipeline dies quietly. Fix: name an owner in the README and have a second person run it once before that happens.
- Holding all of it in a spreadsheet. Manual formulas break silently and nobody can tell what changed. Fix: move the transformation into a script or OpenRefine, where the steps are recorded.
A few habits keep a small pipeline alive. Run the collection and the cleaning as one scheduled job, so a partial download never reaches the output. Keep a short changelog of what the pipeline produced on each date, which is how you reconstruct a number that appears in a published graphic. Review the source once a quarter, since public datasets get retired more often than people expect.
And know when the setup is finished for you. Rebuild or replace it when a second source joins and the two must be joined together, when the story depends on updates within minutes, when the person maintaining it is the only person who can read the code, or when the same cleaning logic has been copied into four separate scripts. A pipeline that only one person understands is a liability with a schedule attached.
Frequently Asked Questions
What is the easiest way to build a data pipeline for a small newsroom?
Start with one CSV you already export by hand, and script only the steps you repeat: download, clean, save. Put the raw file in a timestamped folder, clean it with a spreadsheet formula or a few lines of pandas, and publish it as a Google Sheet or CSV. Add scheduling and checks only after the manual version has worked three times. A weekend is realistic.
Do I need Python or a developer to build a newsroom data pipeline?
Not for a single well-behaved source. Spreadsheet formulas, OpenRefine and a manual export cover most first pipelines. Bring in a developer when the source has no usable download, when you need to join several sources, when the feed must update within minutes, or when the output feeds something readers see directly. The threshold is complexity of the source, not the size of the newsroom.
Should a newsroom use an API, CSV file, or spreadsheet as its data source?
Take whatever is most reliable, in this order: an official API, then a bulk download, then a maintained public page, then a manual export as a last resort. Each step down costs you automation and accuracy. If a dataset is publishable in a spreadsheet, a formal information request often beats scraping and gives you a document to cite when the agency later changes the numbers.
How often should a newsroom data pipeline refresh its data?
Match the source, not your ambition. A dataset updated weekly should run weekly. Daily collection is reasonable for fast-moving public data such as case counts or filings, and hourly only where the story genuinely needs it. Running more often than the source updates wastes effort and invites rate limits. Whichever interval you choose, schedule the run early enough that a failure is still fixable before the deadline.
How can journalists tell whether automated newsroom data is accurate?
Keep the untouched original, keep a dated record of every run, and spot-check a few rows against the source by hand before publication. Never let a transformation silently drop or zero-fill records; log the row count before and after cleaning. If you cannot reconstruct how a published number was produced from the stored files, you cannot defend it when someone disputes it.
When should a newsroom pipeline be rebuilt or replaced?
Rebuild when a second source needs joining to the first, when updates must happen within minutes, when the person who wrote it is the only one who can read it, or when the same cleaning code has been copied into several projects. At that point the maintenance cost exceeds a hosted tool. One source, one output and a documented README are a good reason to keep building it yourself.
Start on Monday by writing the specification for one output file and finding the source for it. If you can do that in an hour, the rest is mechanical: collect, store the original, clean, schedule, check, publish. Get that single pipeline documented well enough for a colleague to run it, and the second one takes an afternoon instead of a weekend.